Mean Variance Portfolio Example
Consider the Markowitz portfolio selection problem, which allocates weights $x \in \mathbb{R}^n$ to $n$ assets so as to maximize returns subject to a variance limit $v_{\max}$:
\[\max_{x} \quad \mu^\top x \quad\text{s.t.}\quad x^\top \Sigma x \;\le\; v_{\max}, \quad \mathbf{1}^\top x = 1,\quad x \succeq 0,\]
where $\mu$ is the vector of expected returns, $\Sigma$ is the covariance matrix, and $x$ must sum to 1 (fully invest the budget). An efficient conic version of this problem casts the variance limit as a second order cone constraint:
\[\| \Sigma^{1/2} x \|_{2} \;\le\; \sigma_{\max}\]
where $\Sigma^{1/2}$ is the Cholesky factorization of the covariance matrix and $\sigma_{\max}$ is the standard deviation limit.
Practitioners often care about an \emph{out-of-sample performance metric} $L(x)$ evaluated on test data or scenarios that differ from those used to form $\mu$ and $\Sigma$. To assess the impact of the risk profile in the performance evaluation, one can compute:
\[\frac{dL}{d\,\sigma_{\max}} \;=\; \underbrace{\frac{\partial L}{\partial x}}_{\text{(1) decision impact}}\; \cdot\; \underbrace{\frac{\partial x^*}{\partial \sigma_{\max}}}_{\text{(2) from DiffOpt.jl}},\]
where $x^*(\sigma_{\max})$ is the portfolio that solves the conic Markowitz problem under a given risk limit.
Define and solve the Mean-Variance Portfolio Problem for a range of risk limits
First, import the libraries.
using Test
using JuMP
import DiffOpt
using LinearAlgebra
import SCS
using Plots
using Plots.Measures
Fixed data
Training data (in-sample)
Σ = [
    0.002 0.0005 0.001
    0.0005 0.003 0.0002
    0.001 0.0002 0.0025
]
μ_train = [0.05, 0.08, 0.12]
3-element Vector{Float64}:
0.05
0.08
0.12Test data (out-of-sample)
μ_test = [0.02, -0.3, 0.1] # simple forecast error example3-element Vector{Float64}:
0.02
-0.3
0.1Sweep over σ_max
σ_grid = 0.002:0.002:0.06
N = length(σ_grid)

predicted_ret = zeros(N)                 # μ_train' * x*
realised_ret = zeros(N)                 # μ_test'  * x*
loss = zeros(N)                 # L(x*)
dL_dσ = zeros(N)                 # ∂L/∂σ_max  from DiffOpt

for (k, σ_val) in enumerate(σ_grid)

    # 1) differentiable conic model
    model = DiffOpt.conic_diff_model(SCS.Optimizer)
    set_silent(model)

    # 2) parameter σ_max
    @variable(model, σ_max in Parameter(σ_val))

    # 3) portfolio weights
    @variable(model, x[1:3] >= 0)
    @constraint(model, sum(x) <= 1)

    # 4) objective: maximise expected return (training data)
    @objective(model, Max, dot(μ_train, x))

    # 5) conic variance constraint  ||L*x|| <= σ_max
    L_chol = cholesky(Symmetric(Σ)).L
    @variable(model, t >= 0)
    @constraint(model, [t; L_chol * x] in SecondOrderCone())
    @constraint(model, t <= σ_max)

    optimize!(model)

    x_opt = value.(x)
    println("Optimal portfolio weights: ", x_opt)

    # store performance numbers
    predicted_ret[k] = dot(μ_train, x_opt)
    realised_ret[k] = dot(μ_test, x_opt)

    # -------- reverse differentiation wrt σ_max --------
    DiffOpt.empty_input_sensitivities!(model)
    # ∂L/∂x   (adjoint)  =  -μ_test
    DiffOpt.set_reverse_variable.(model, x, μ_test)
    DiffOpt.reverse_differentiate!(model)
    dL_dσ[k] = DiffOpt.get_reverse_parameter(model, σ_max)
end
Optimal portfolio weights: [3.740836100186848e-15, 0.01855192680505087, 0.039192905615433635]
Optimal portfolio weights: [7.857679140744005e-8, 0.037318469876372766, 0.07878224485177933]
Optimal portfolio weights: [8.161646797677368e-8, 0.05572327459984616, 0.11766655642972719]
Optimal portfolio weights: [3.257780598980871e-9, 0.07419973293183461, 0.15676613209085888]
Optimal portfolio weights: [2.692558265416144e-13, 0.09275963401543982, 0.19596452818622248]
Optimal portfolio weights: [1.8507557225112304e-10, 0.11131170034093736, 0.23515766397386917]
Optimal portfolio weights: [1.9660094887252786e-9, 0.1298630489810886, 0.27434989103567925]
Optimal portfolio weights: [2.1781466569329498e-8, 0.14840416819642172, 0.31353911882050856]
Optimal portfolio weights: [4.475975103257303e-10, 0.16696727774635967, 0.3527360479375704]
Optimal portfolio weights: [1.5546087067713907e-11, 0.18551927173537994, 0.39192905413480067]
Optimal portfolio weights: [-6.838740218952143e-11, 0.2040711997516712, 0.4311219608967614]
Optimal portfolio weights: [-2.510843028319289e-9, 0.222616577935894, 0.4702995249574812]
Optimal portfolio weights: [-6.120332127060743e-9, 0.2411696442318598, 0.5095002284172712]
Optimal portfolio weights: [-2.3775719802070063e-8, 0.25961756418886867, 0.5486590228010882]
Optimal portfolio weights: [-3.912835894787744e-8, 0.2781683316409077, 0.587663391848101]
Optimal portfolio weights: [7.905999576396687e-15, 0.29683082888214274, 0.6270864898460246]
Optimal portfolio weights: [1.8316369098515223e-9, 0.31540726891188603, 0.6662741900425576]
Optimal portfolio weights: [-8.546819534212303e-8, 0.2461528663955905, 0.7538562211891018]
Optimal portfolio weights: [6.410019125839355e-9, 0.17185848997283718, 0.8281406987504184]
Optimal portfolio weights: [-4.886180840302956e-8, 0.11373267208019489, 0.8862729677156791]
Optimal portfolio weights: [-3.1972203313174196e-12, 0.06232555996974516, 0.9376744392433418]
Optimal portfolio weights: [-9.42485461354415e-8, 0.016019269832172833, 0.9839865049635247]
Optimal portfolio weights: [-1.235089618790137e-5, -2.6537002585992486e-5, 1.0000779617945676]
Optimal portfolio weights: [-8.998811470897685e-8, -8.037441616877137e-8, 1.0000003256229277]
Optimal portfolio weights: [6.46137747144075e-11, -5.83401672800922e-10, 1.000000000642846]
Optimal portfolio weights: [-4.911186521212683e-13, -2.2176626937727845e-13, 1.0000000000005167]
Optimal portfolio weights: [-1.5288033466468397e-9, -1.5856139050008396e-9, 1.000000005167348]
Optimal portfolio weights: [8.85642111137959e-13, 4.569882588754208e-13, 0.9999999999988236]
Optimal portfolio weights: [-2.344060457886412e-12, -5.775365159141289e-12, 1.0000000000068752]
Optimal portfolio weights: [1.5260358133466282e-13, 2.407224529843491e-13, 0.9999999999995876]Results with Plot graphs
default(;
    size = (1150, 350),
    legendfontsize = 8,
    guidefontsize = 9,
    tickfontsize = 7,
)
(a) predicted vs realised return
plt_ret = plot(
    σ_grid,
    realised_ret;
    lw = 2,
    label = "Realised (test)",
    xlabel = "σ_max (risk limit)",
    ylabel = "Return",
    title = "Return vs risk limit",
    legend = :bottomright,
);
plot!(
    plt_ret,
    σ_grid,
    predicted_ret;
    lw = 2,
    ls = :dash,
    label = "Predicted (train)",
);
(b) out-of-sample loss and its gradient
plt_loss = plot(
    σ_grid,
    dL_dσ;
    xlabel = "σ_max (risk limit)",
    ylabel = "∂L/∂σ_max",
    title = "Return Gradient",
    legend = false,
);

plot_all = plot(
    plt_ret,
    plt_loss;
    layout = (1, 2),
    left_margin = 5Plots.Measures.mm,
    bottom_margin = 5Plots.Measures.mm,
)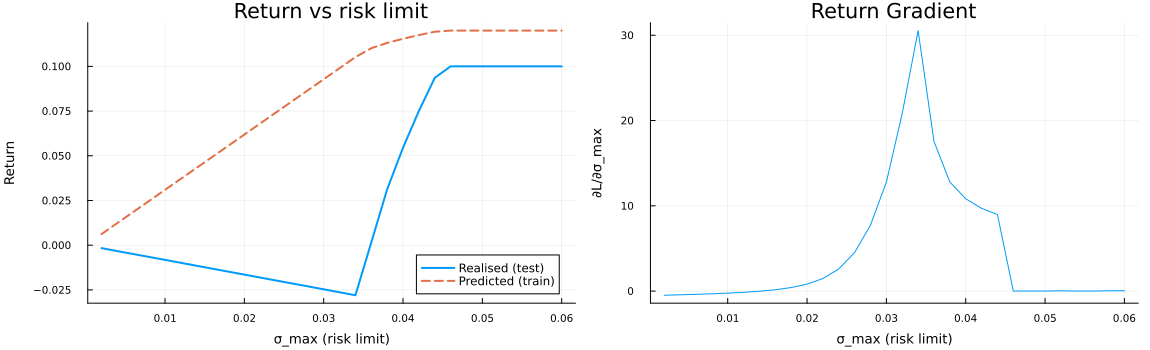
Impact of the risk limit $\sigma_{\max}$ on Markowitz portfolios. Left: predicted in-sample return versus realized out-of-sample return. Right: the out-of-sample loss $L(x)$ together with the absolute gradient $|\partial L/\partial\sigma_{\max}|$ obtained from DiffOpt.jl. The gradient tells the practitioner which way—and how aggressively—to adjust $\sigma_{\max}$ to reduce forecast error; its value is computed in one reverse-mode call without re-solving the optimization for perturbed risk limits.
This page was generated using Literate.jl.